

Shall We Read
Get A Personalized Recommendation
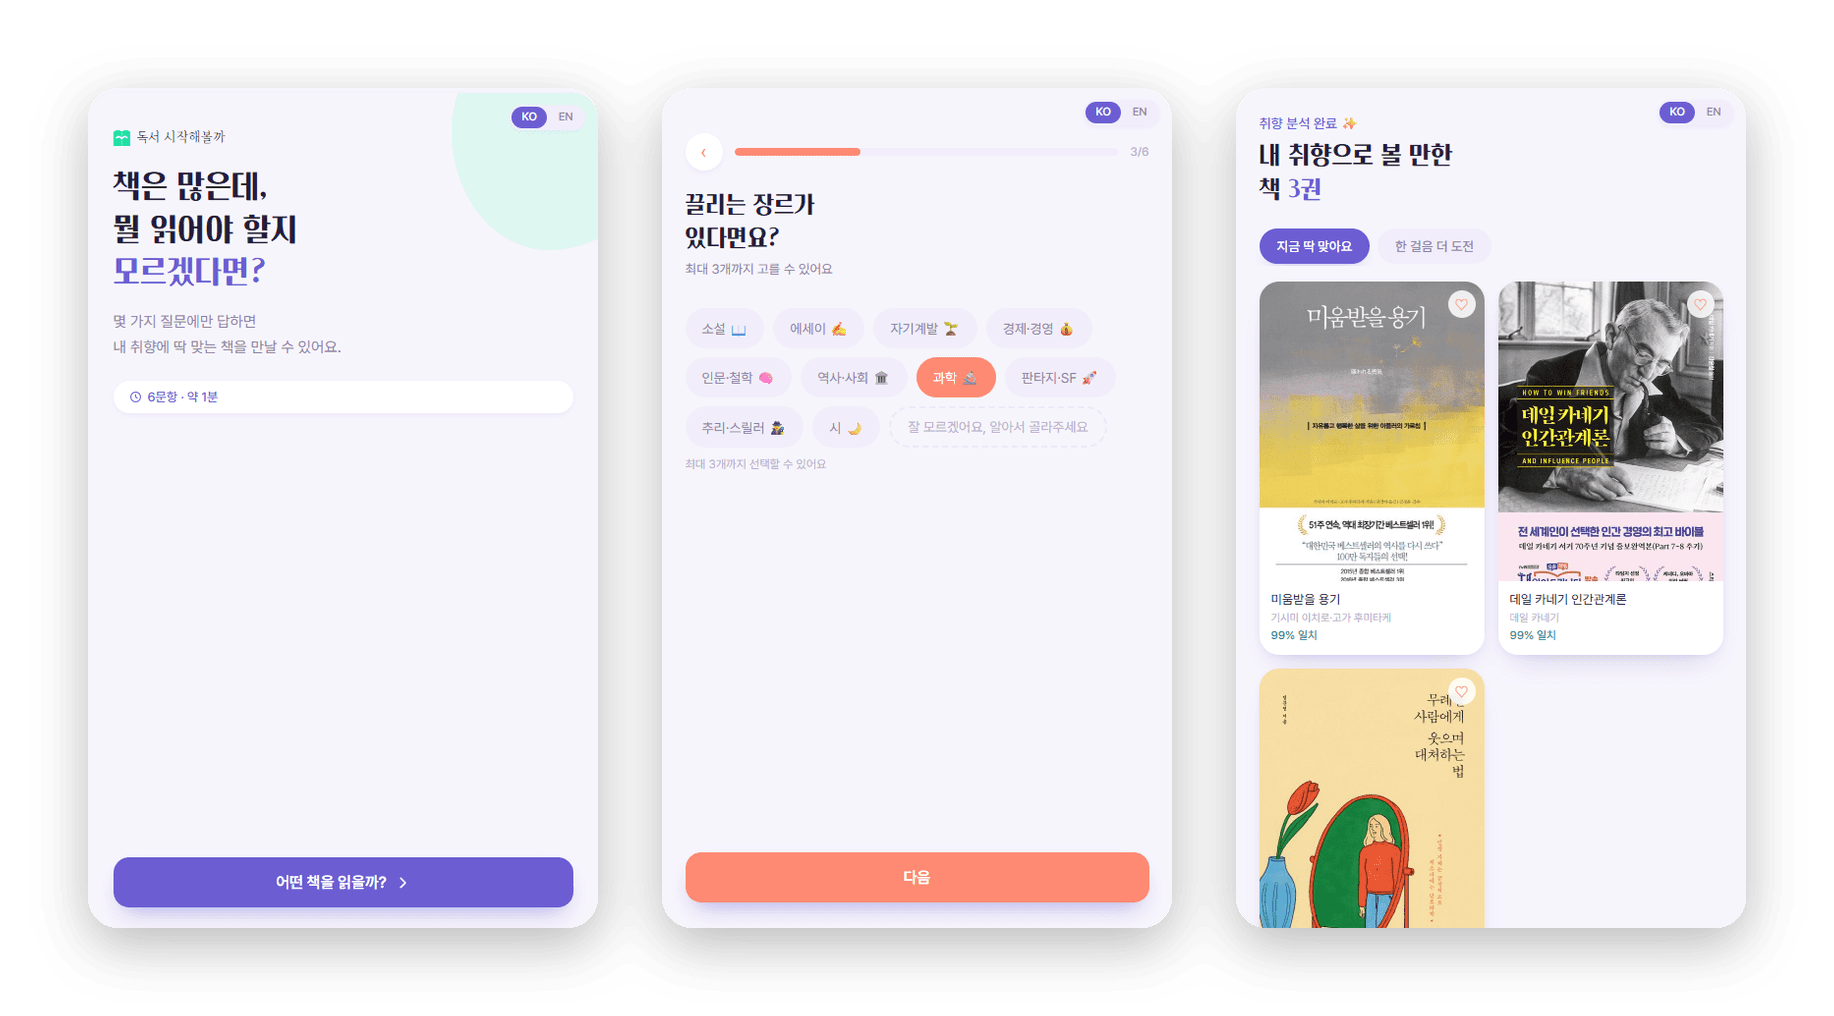
A Korean-language book recommendation quiz that asks what you want to feel or gain from a book, not just which genre you like. It has reached up to 40 daily users and earns through Coupang affiliate links. Built solo as an experiment in agent-driven development.
- Claude Code
- Next.js
- React
- JS
- TailwindCSS
Shall We Read is a fun book recommendation service. You answer a set of questions and get a suggestion for what to read. Some of the questions are simple, like which genre you prefer, but others ask for deeper, more specific information, such as what you are looking to gain or feel when reading a book. This was an intentional design decision to set it apart from the more generic book recommendation services that already exist.
The app has reached up to 40 daily users and has generally received positive feedback. Users commented things like “fun idea!” when sharing the website on Threads. Their main concern was the small catalog of books. This was very much expected, as I intentionally took a small set of books for the first development cycle. The second cycle prioritizes refining the recommendation algorithm and adding a larger book catalog. As of this writing, the second development cycle is still in progress.
The business model is based on Coupang affiliate links. Every time a user buys a book through a recommendation, I get a small percentage. Until you are a Coupang partner, the affiliate links must be generated manually, which also makes it harder to add a large set of books from the get-go.
Workflow
I developed the website independently and used Claude's Opus 5 model to power a lot of the implementation. I also took the opportunity to experiment with agentic workflows, using Claude Code's GitHub Actions integration to have it work on issues directly through GitHub. I also experimented with different popular sets of Claude skills, such as Matt Pocock's skills for closely guided agentic development.
The hardest part of developing this app was getting aligned with the agents. When pivoting quickly on ideas, the agents had a tendency to keep old logic and ideas, which hindered the accuracy of implementing new ones. For example, at one point an agent failed to properly change the recommendation algorithm, despite me explicitly telling it what to do.
My current solution is to manage the context carefully: create a larger plan with a few planning agents, then implement the plan one step at a time with a clean context. Implementation can of course be done concurrently, for example with GitHub workflows, unless there are blocking issues.
Recommendation logic
The recommendation logic is based on filters and a scoring process. Each book is associated with a fixed set of data. Here is an example:
{
  title: '죽고 싶지만 떡볶이는 먹고 싶어',
  author: '백세희',
  year: 2018,
  genre: ['essay'],
  ratings: {
    need: { comfort: 3, fun: 1, knowledge: 1, growth: 1, trend: 1, habit: 2 },
    priority: { easy: 3, depth: 1, bestseller: 3, happy: 1 },
    topic: {
      money: 0, relationship: 1, career: 0, mindcare: 3,
      society: 0, science: 0, history: 0, selfunderstand: 2,
    },
  },
  trendRatedAt: '2026-09-24',
  avoid: ['heavy'],
  difficulty: 1,
  length: 'short',
}
Genre is one example of a filter: it narrows the catalog down to books in the genre the user selects. Ratings and topic contain the values used in the scoring process. A score is calculated for each book that passes the filters, based on how the user answers. Books with higher numbers in the ratings and topics the user preferred get a higher score, and the book with the highest score is the top recommendation.